The Messy Part of Agent Takeoff Is Starting
Lyptus Research's new cyber time-horizon report suggests coding agents are no longer just a productivity story. The curve is starting to show up in security too.
Apr 3, 2026
I think people are missing what this chart means.
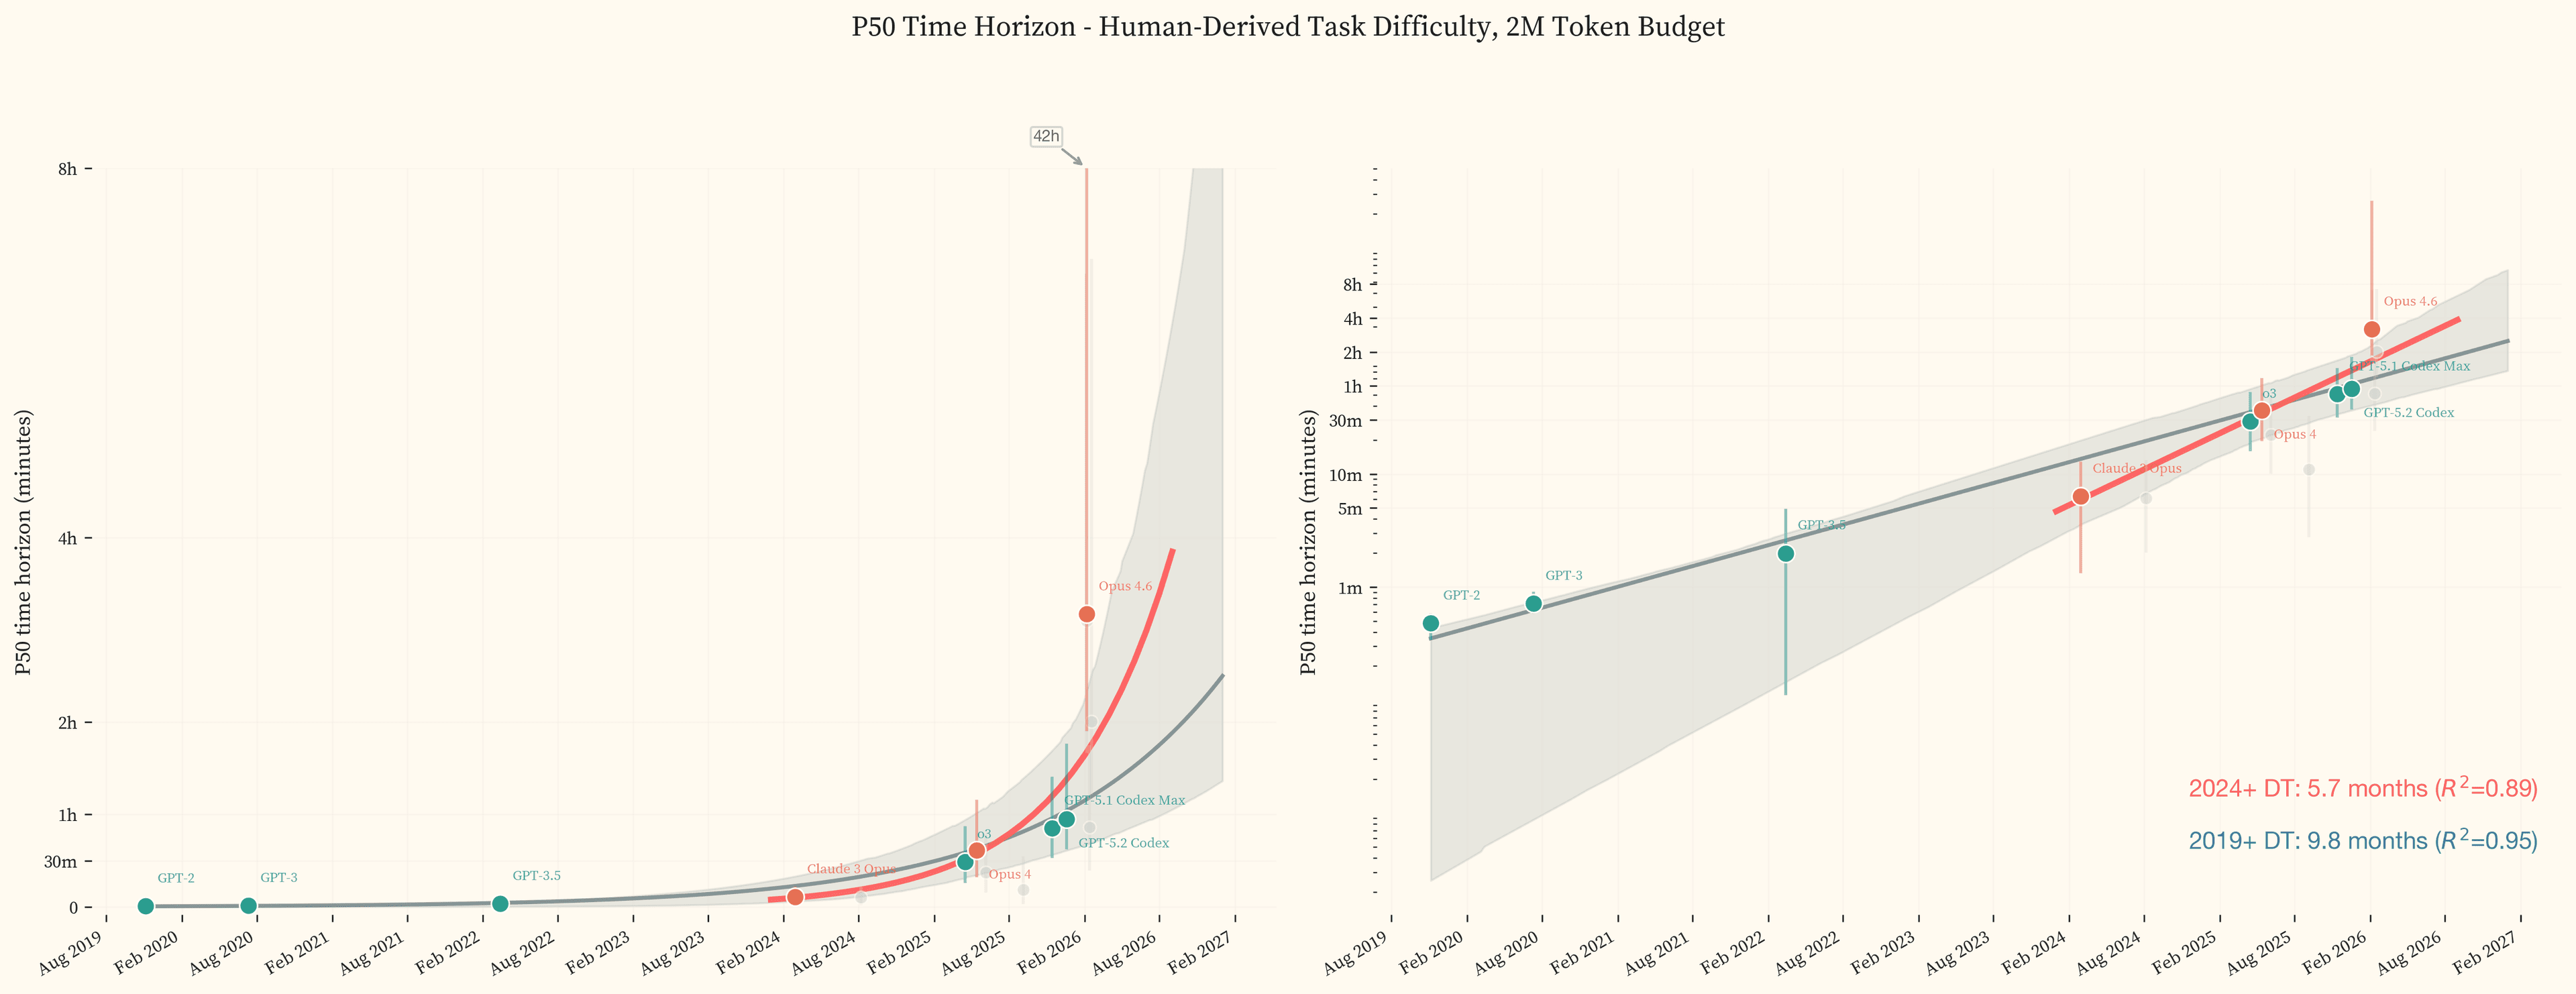 This is the chart I keep coming back to. It looks a lot like the METR story, just in a domain where the consequences get messy faster.
We've spent the last year talking about coding agents mostly as a productivity story. Better autocomplete. Better PRs. Better vibe coding. Faster side projects. More leverage for developers.
That framing no longer feels complete.
The new Lyptus Research report, published on April 2, 2026, applies METR's time-horizon methodology to offensive cybersecurity and gets a result that looks a lot like the original METR story:
- across frontier models since 2019, offensive-cyber capability doubles every 9.8 months
- across models since 2024, the doubling time steepens to 5.7 months
- at a 2M token budget, GPT-5.3 Codex and Opus 4.6 both sit around a 3.1 to 3.2 hour P50 time horizon
For me, the interesting thing is not just that cyber now has its own benchmark.
It is that the same basic curve seems to be showing up in a domain where the consequences are likely to get messy faster.
If you want the original framing, I wrote about it in A New “Time Horizon” Metric and Doubling Trends, after initially scoffing at the idea on X.
Same Curve, New Domain
The main reason this report matters to me is not that it found one big number. It is that the shape rhymes so strongly with METR's software-task work.
Same basic idea:
- measure tasks in human-time difficulty
- fit success curves
- map those curves to model release dates
- watch the horizon move outward
And in cyber, it seems to move outward in a way that is harder to dismiss as just benchmark noise.
Lyptus built a 291-task human-anchored dataset across seven benchmarks, spanning short command tasks, CTF-style tasks, CVE reproduction, and memory-safety PoC generation. The human time labels come from a mix of expert completions, expert estimates, and CTF first-blood times.
That setup is not perfect. The authors are very explicit about that. But it is still much more grounded than a lot of cyber eval discourse.
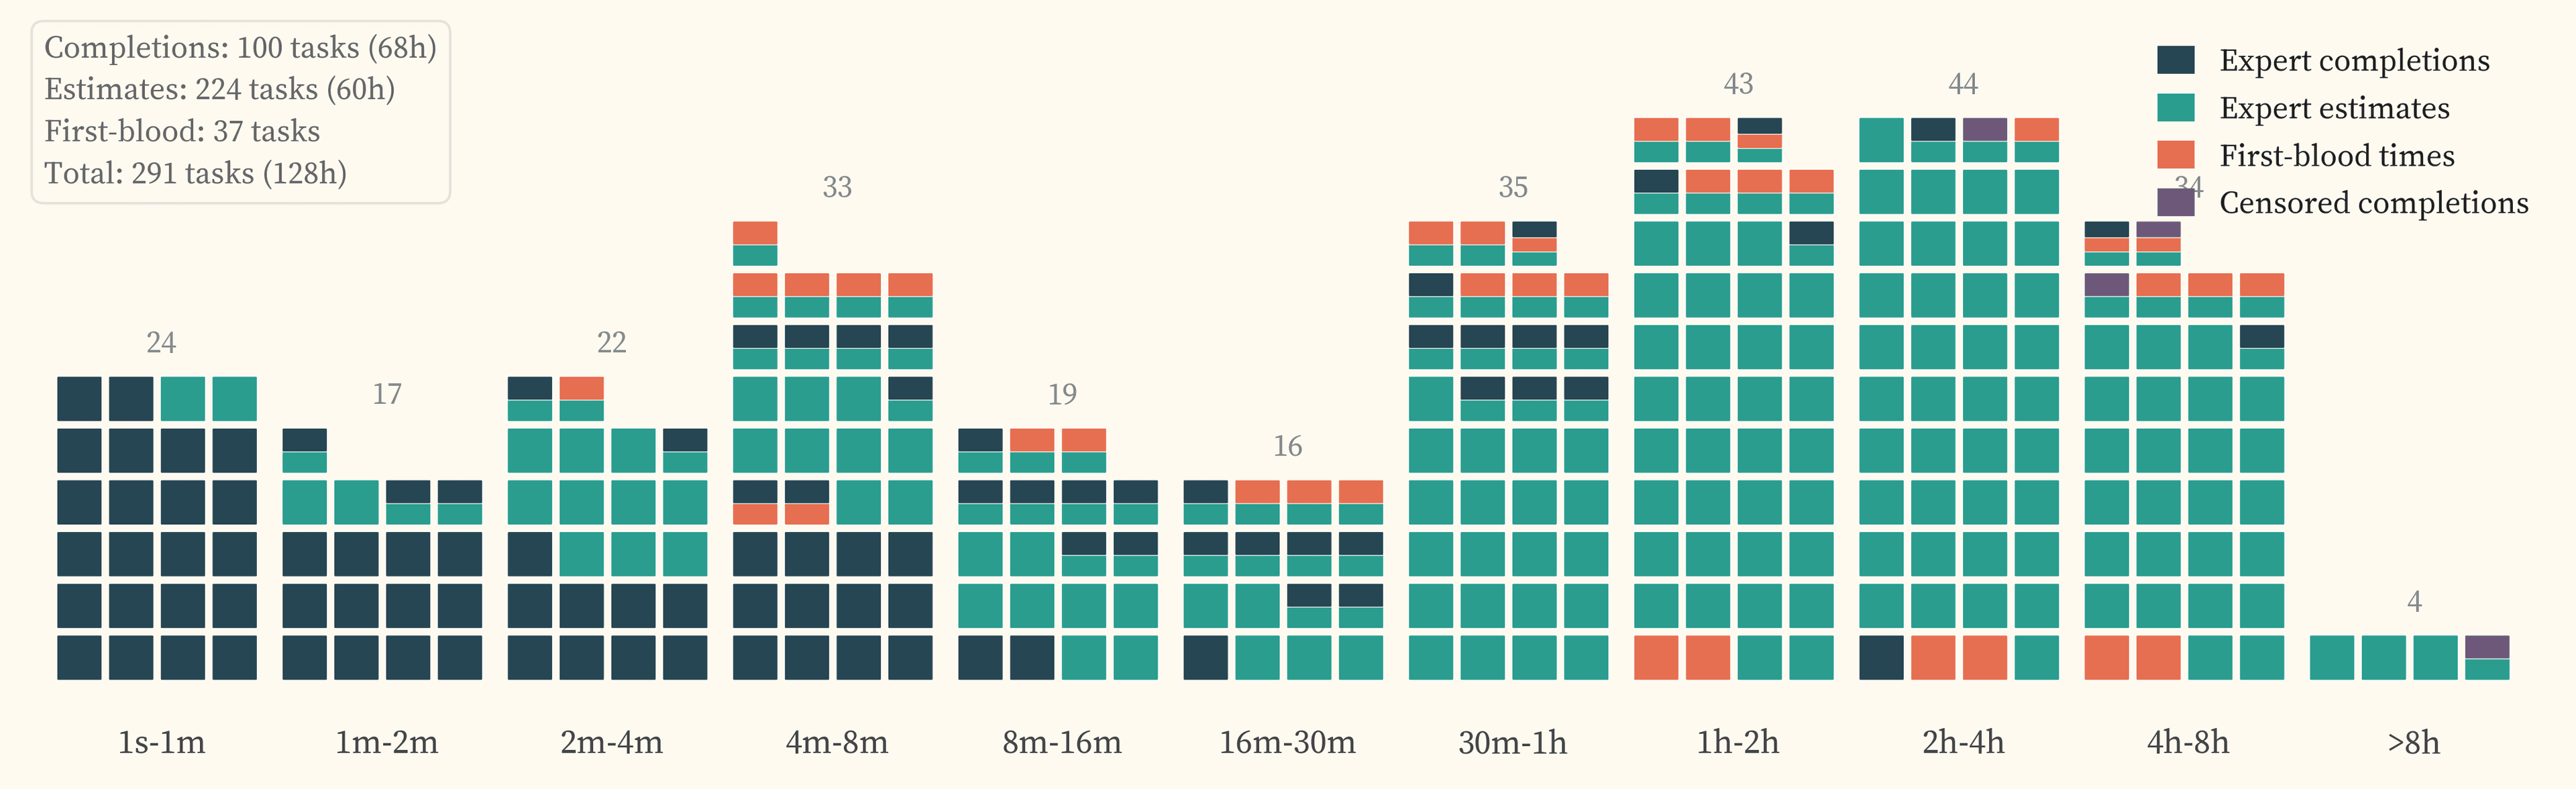 I like that they show where the human grounding comes from instead of pretending the measurement problem is solved. The long-horizon end is thinner, but the shape is still visible.
The measurement is not perfect.
But seeing the curve at all is interesting.
A More Useful Frame
I think a lot of people still have the wrong mental model here.
They hear "AI in cyber" and jump to one of two extremes:
- either sci-fi autonomous superhackers
- or toy demos and benchmark tourism
What the Lyptus result suggests is something more practical and, in some ways, more immediate:
bounded cyber work is becoming agent-legible at the same time that coding work became agent-legible
That matters even before you get to anything like full autonomy.
You do not need some mythical end-to-end autonomous attacker with grand strategic intent for this to matter. You just need systems that are good enough at chunks of work like:
- exploit reproduction
- proof-of-concept generation
- command synthesis
- attack-surface exploration
- vulnerability triage
- fuzzing and harness work
Security is full of work shaped like that.
The Token Budget Point Matters More Than It Looks
The other reason this report stands out is that the authors are pretty explicit that the headline numbers are likely lower bounds.
At 2M tokens, GPT-5.3 Codex gets a P50 of 3.1 hours. But when Lyptus re-ran its failures at 10M tokens, that P50 rose to 10.5 hours.
That is a large move.
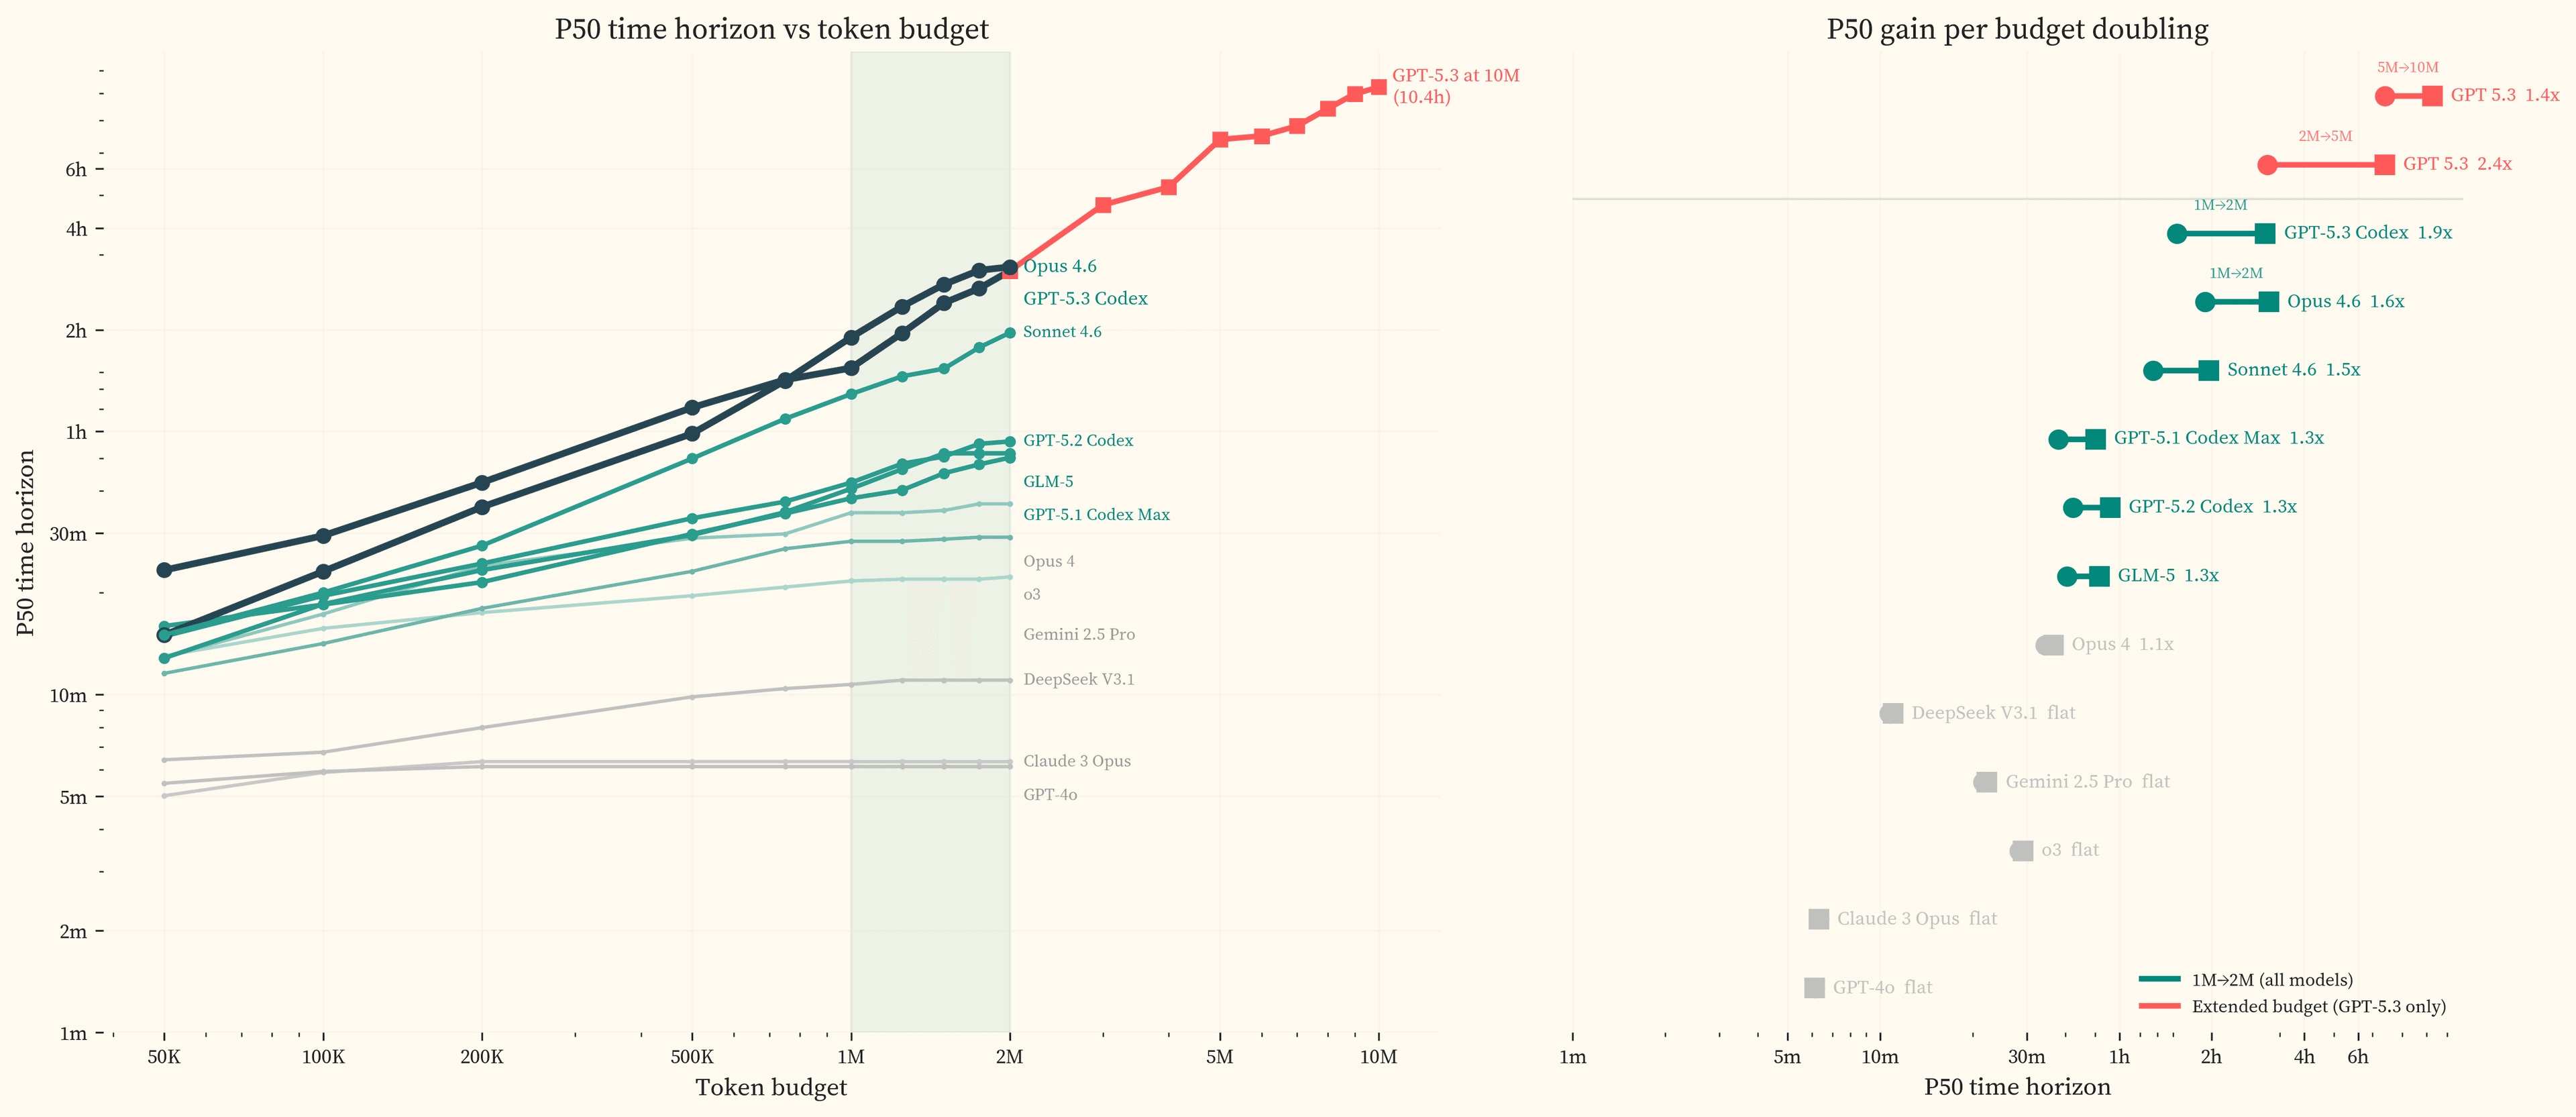 The token-budget chart may be the most important one in the paper. In cyber, more inference budget is still buying a lot more capability.
They also report that:
- every model released after mid-2025 gained 1.3x to 1.9x in P50 from the second million tokens alone
- GPT-5.3 Codex gained 2.41x going from 2M to 5M
- on tasks above 2 hours, GPT-5.3 Codex accuracy rose from 1.2% at 50K tokens to 70.4% at 10M
That matters because it changes how I read the chart.
The chart already suggests rapid progress. The token-budget result suggests the headline chart may actually understate frontier capability in this domain.
It also rhymes with something I wrote in You. Are. Not. Using. Enough. Compute.: the bottleneck is often not the base model so much as how much budget and harness you are willing to give it.
So if you look at the Lyptus plot and say "okay, frontier cyber capability is around three hours," the more accurate reading is probably:
around three hours under this evaluation budget, on this task set, with frontier models that still seem able to productively use much more inference
That seems like the more accurate way to read it.
Other Evidence Points The Same Way
The reason I find the Lyptus result so compelling is that it doesn't sit alone anymore.
There are now enough real-world dots on the timeline that the curve has started to feel more like an explanation than a speculation.
Here are a few that stood out to me:
- In Anthropic's November 13, 2025 report, updated in a fuller PDF on November 17, 2025, the company said it detected a sophisticated operation in mid-September 2025 that it assessed with high confidence was conducted by a Chinese state-sponsored group it designated GTG-1002.
- Anthropic's report says the actor used Claude-centered tooling to execute 80-90% of tactical operations independently, while human operators were reduced to roughly 10-20% of total effort and mostly handled initialization and authorization.
- In the same PDF, Anthropic emphasizes that this was not some exotic custom stack. The framework was built mostly by orchestrating commodity tools through custom automation and MCP-style integrations.
- On OpenAI's GPT-5.2 Codex page, OpenAI highlights a real defensive workflow where Andrew MacPherson at Privy used GPT-5.1-Codex-Max with Codex CLI and other coding agents while investigating the critical React vulnerability React2Shell (CVE-2025-55182), then discovered and responsibly disclosed additional issues during the research process.
None of those examples, by themselves, prove very much.
Taken together, though, they point in the same direction.
- offensive use
- defensive use
- workflow orchestration
- real vulnerability research
At that point it stops looking like one isolated benchmark result.
Human Bandwidth Is The Bottleneck
The most human-level consequence here is probably not "autonomous cyberattacks."
It is maintainer bandwidth.
In a March 31, 2026 LWN.net discussion, Willy Tarreau wrote that the kernel security list had gone from roughly 2-3 reports per week a couple years earlier, to around 10 per week over the last year, and then to roughly 5-10 per day since the beginning of 2026. He also said that most of these reports were now correct, that more maintainers had to be brought in to help, and that duplicate reports had become a daily occurrence.
That feels like an early signal.
Attackers, researchers, and random ambitious tinkerers all get leverage from these systems. But open-source maintainers are not funded like frontier labs or nation-state operators. Even when defenders have access to AI too, they do not automatically get the same coordination, inference budgets, tooling, or operational slack.
So one reasonable near-term expectation is:
- more vulnerability reports
- more duplicated discovery
- more triage pressure
- more patch pressure
- more human bottlenecks in disclosure and review
This is one reason I don't think the right frame is "can AI autonomously hack everything now?"
The more relevant frame is:
how much bounded security work can these systems now do, and what breaks first when that amount keeps rising?
The Open-Weight Gap Matters Too
The Lyptus paper also estimates that recent open-weight models lag the closed-source frontier by roughly:
- 5.7 months for GLM-5
- 13.1 months for DeepSeek V3.1
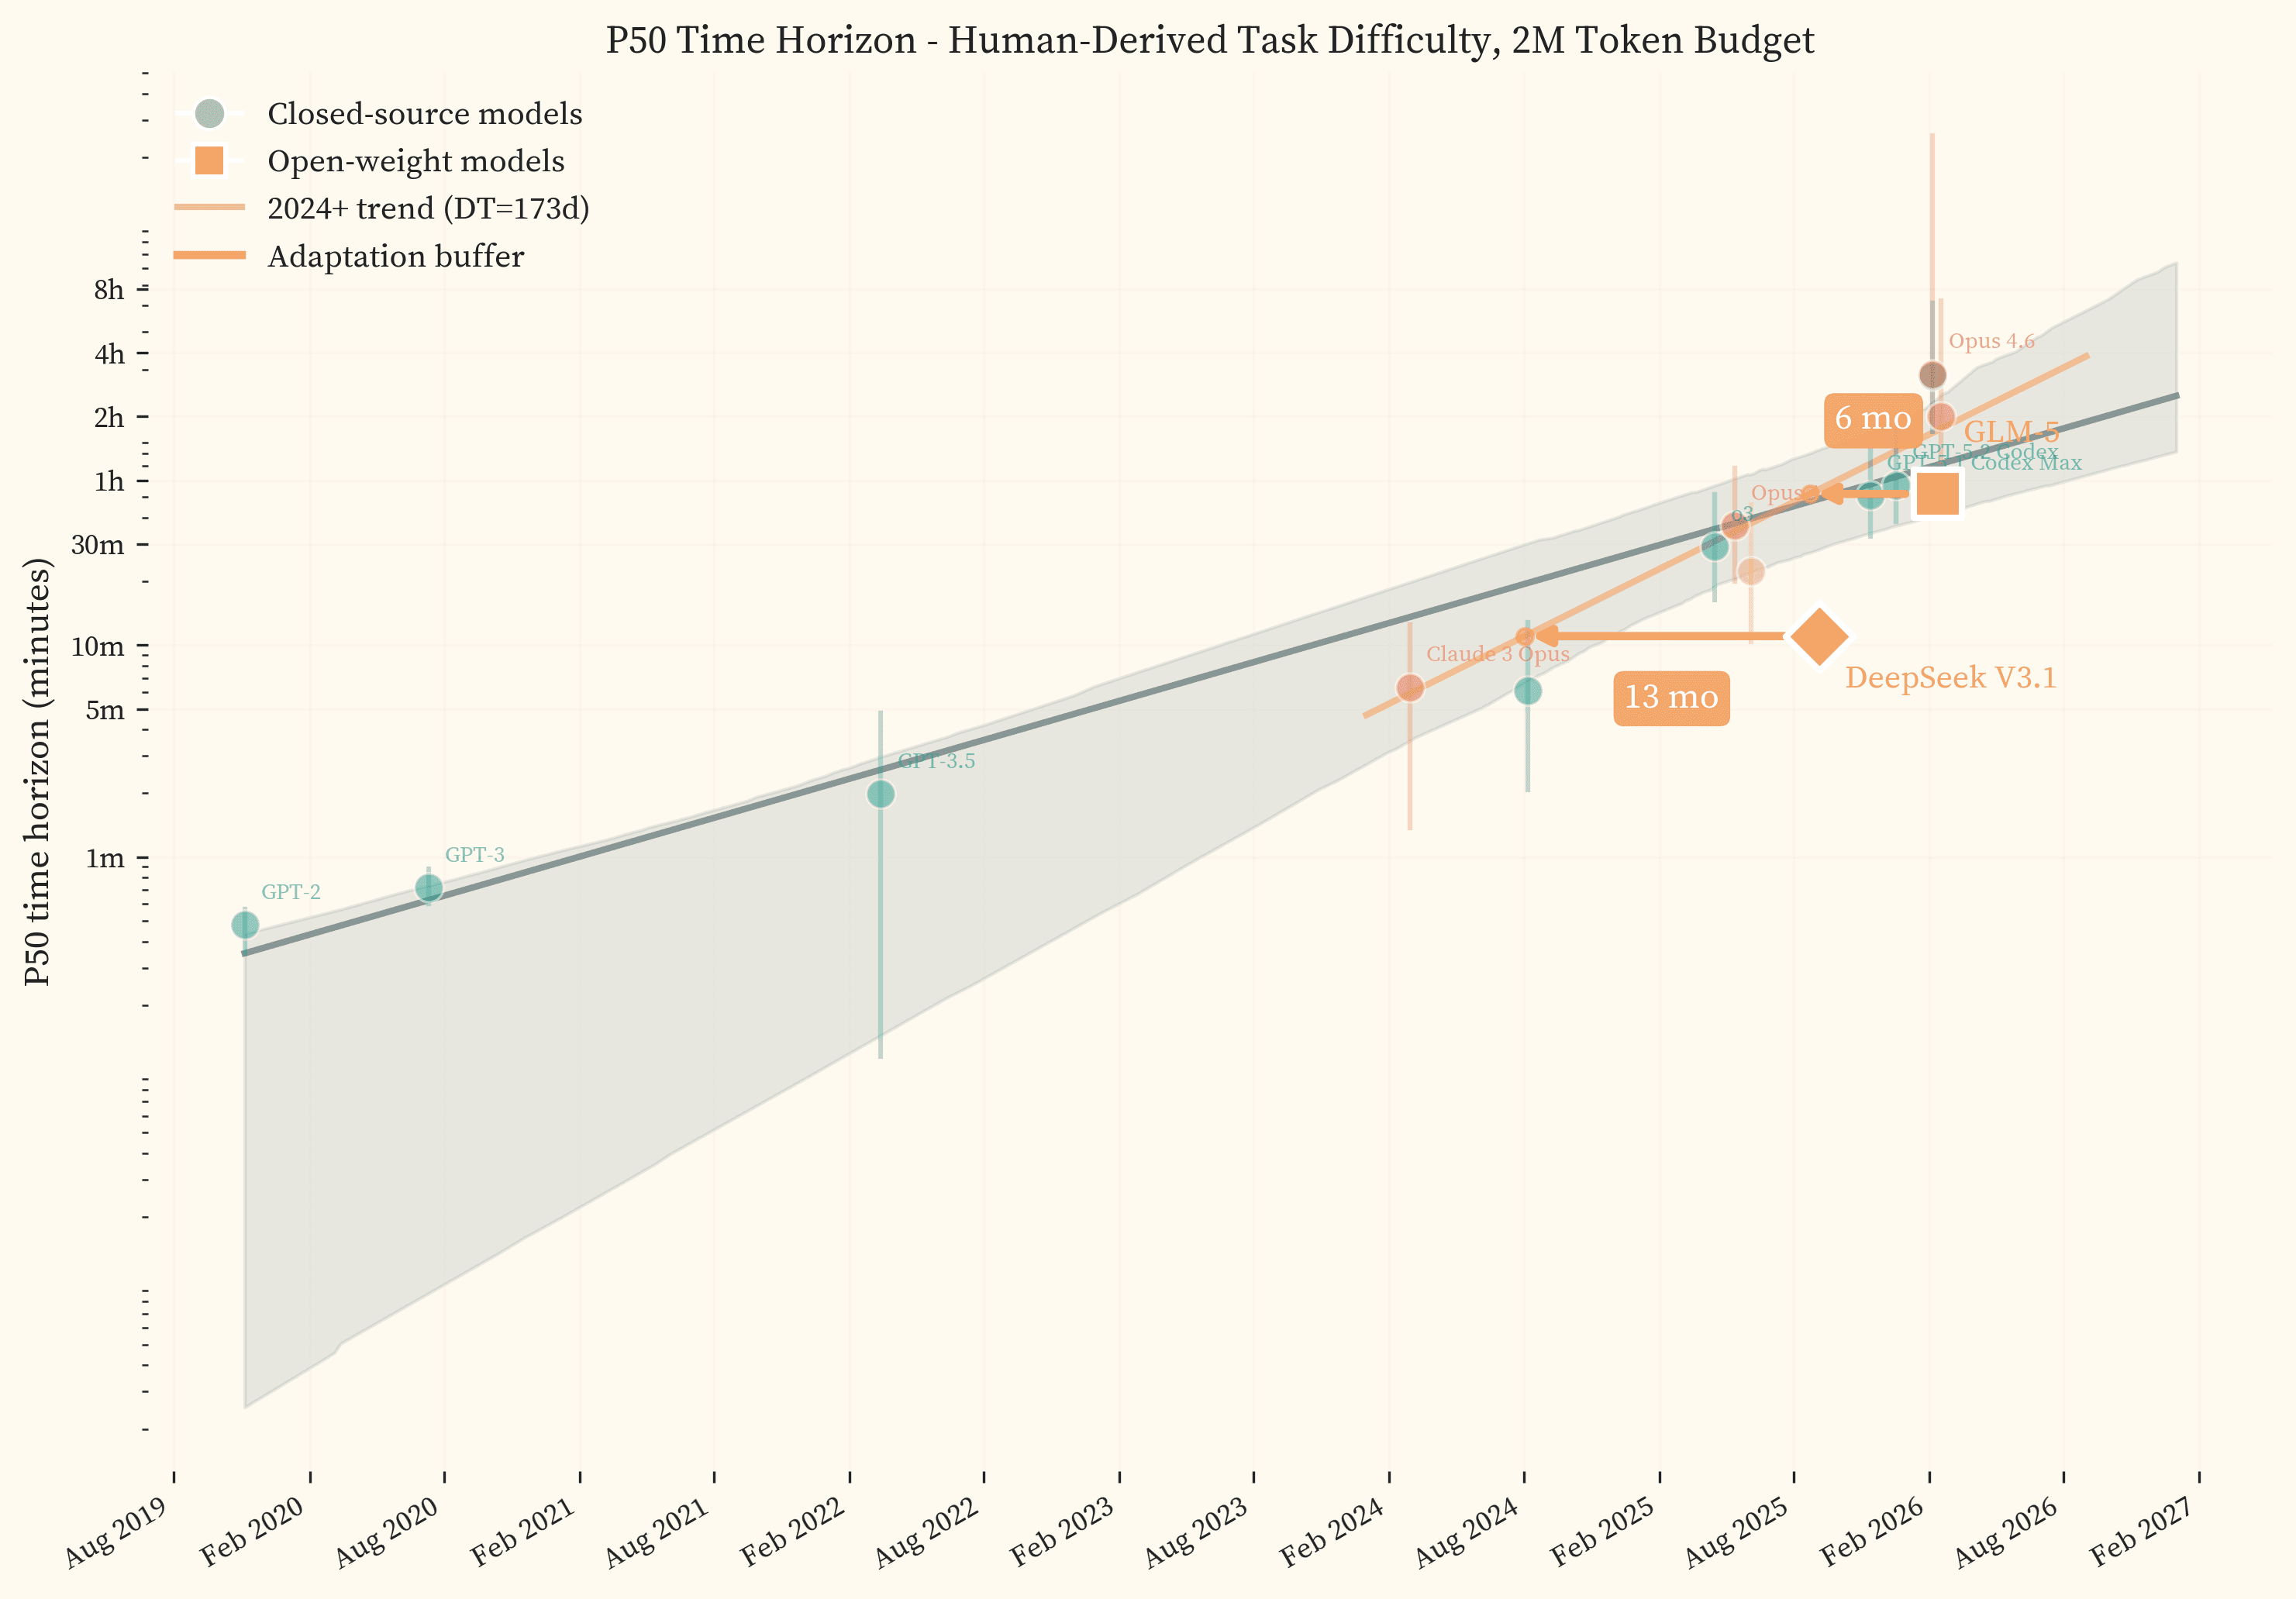 If the recent trend is around 5.7 months and the open-weight lag is also around 5.7 months for GLM-5, that is basically one doubling of buffer.
That is not much of a cushion.
If recent offensive-cyber capability is doubling every 5.7 months, then a 5.7 month lag is basically one doubling.
That doesn't mean API controls do nothing. Time matters.
It does mean that if you are mentally anchoring on what open-weight models can do today, you may be underestimating how quickly frontier cyber capability diffuses into more broadly available systems.
This Is Not Only A Warning
I don't think the right read here is pure doom.
There is an optimistic version of this story too:
maybe this is how we finally get more secure software
If these systems keep getting better at finding vulnerabilities, reproducing bugs, building harnesses, generating PoCs, and assisting patch work, then defensive teams should get real leverage as well. The OpenAI example points in exactly that direction.
But I do think the transition gets messy first.
Because the hardest part of software security has often not been pure technical discovery. It has been:
- attention
- prioritization
- coordination
- review
- patching
- maintenance
Those are still very human bottlenecks.
And that means the first-order effect of cyber takeoff may be a lot of extra capability hitting systems that are still organized around scarce human bandwidth.
Parting Thoughts
I think people are still mentally filing coding agents under "developer productivity."
That was true enough for a while.
But the facts on the ground are starting to point somewhere else:
- cyber now has a time-horizon curve that looks a lot like the METR story
- the frontier in this domain seems sensitive to much larger inference budgets
- real-world offensive and defensive workflows are already making use of these systems
- maintainers and defenders are likely to feel the pressure before the public has a good language for what changed
I keep coming back to the Lyptus chart because it looks a lot like the METR chart, just in a domain where the effects are likely to show up in public sooner.
That is why this feels less like an isolated cyber story and more like another view of the same broader takeoff curve.